

will probably be edited. I published this at the gym, after thinking “eff it".
Context
In the past year, we’ve seen the release of considerable evolution in large language models:
November 2025: A step change in the utility of “agents” (with LLMs from Anthropic, Google & OpenAI)
June 2026: The release of Fable, a very capable and very large (6 Trillion Parameter) model. Notably, the model was uniquely capable of finding security vulnerabilities.
August 2026: Jeff Dean notes that human level performance for these models on some tasks is already here (before leaving to start an AI startup). OpenAI describes how during testing (without safeties encoded in the model), their models inadvertently hacked HuggingFace.
For me personally, I’ve built some software projects via agents (h10s.app, a message scheduler, breathing relaxation app, multiple plugins for the Pi harness, an agent harness, and a library for making agents. I’ve manually written a link shortener as well as professionally used Claude CLI and related tools fairly significantly).
Together, this leaves a singular impression: It is possible to build an agentic system that exceeds the capabilities of humans. This creates, for the first time, an alternative design for product delivery where the absolute majority of work done to improve the product is automated. This creates some key questions, such as:
What does the (alternate) delivery of value look like?
What role do humans play in this system?
How do you orchestrate this at larger scales and for larger product suites?
This paper exists to help provide a reference example of what a “future” organization might look like.
Assumptions
There are a couple of long standing assumptions I have:
Business Success = ƒ(Experimentation Frequency)
Any business is essentially an optimization loop (if large, and occasionally, unwieldy one). It attempts to trade off between a variety of outcomes, but its ability to do so gated fundamentally on how much it learns and innovates better working models (as well, willingness to change and ability to deliver stable & efficient operations).
LLM tokens will decrease in price
While there are still large prices for frontier models like Opus 5 or Mythos, those prices are already interesting to compare against humans who deliver similar value but without the same fungibility or scalability (up & down), and models such as Kimi K3 deliver frontier value for ~⅓ the price. There’s enormous capital expenditure right now racking both GPU and more specialized ASIC chips (e.g. TPU, Cerebras Wafer) with the current prices assumed to be somewhat offsetting that investment.
Vision
An extreme view on what value delivery might look like in future is as follows:
Jan is a maintainer of the “widget loop checkout” loop; one of a team of 3. He arrives at his desk, opens his laptop and opens up his loop insights view. He can see different work items in stages of delivery, from ideation, research, ux & technical design, delivery and release, with most of the work being in release as it is waiting to prove its business case with real customers.
The report points out the broad status of work, and items that need a human review. Of the 8 releases currently going to production, two are problematic — one appears to be driving an increase in total revenue through increased advertisement, but decreases conversion at the checkout. The release is paused pending guidance. He opens a chat with the lead agent, reads the case summary, and gives the guidance to abandon the change; the lower conversion might impact CLV more than the revenue will gain. He cc’s the team lead directly in the chat. The second change is paused with a flag for legal review — a legal analysis agent picked up that a recently introduced law in this market requires tipping only after the order is delivered. This change adjusts the tipping UI, but the current production app also has this problem. Jan marks this change should proceed, and schedules a new task to create a feature flag to disable pre-purchase tipping in specific markets. He marks this task “urgent” so it goes to the head of the line, ensuring it’s only blocked by clear CX regressions or technical faults.
After reviewing the in flight requests, Jan opens the work proposals UI. The agents have prepared 6 potential improvements, mostly minor UX and accessibility improvements. In one, marked “Urgent”, a “Fastvertising” agent has noted that Robert Downey Junior is reprising a role in Marvel as “Doctor Doom”. It proposes an advertising campaign for a new product, with slogans like “More surprising than Downy Doom”. Jan approves it, with guardrails that track click-through conversion in the case the jokes don’t land well with the customers. He pushes it forward, but finds surprisingly, it was rejected by a quality control agent. It turns out, another part of the UI — the home page — already picked up a similar campaign, and this would conflict.
Jan reviews the 3 changes that are awaiting release. Two are simple changes, covered by unit tests and with clear criteria to govern the release (a so-called “change set”). However, one is more extensive, changing the API behavior. Jan approves the first two, and marks the third for a more detailed review later to understand which clients depend on this API, and how they’ll need to be adjusted.
Jan then sets about reviewing core business KPIs. He notes that in one market, there’s extremely spikey user behavior — periods of nothing, and then substantial orders. He dispatches an agent to investigate. It finds there are no significant differences between that market and others. Jan jumps into Google to search for things happening in that local market, and quickly finds it — there was a shock election results in that market, and the timings for orders land during breaks in coverage.
After thinking about this a while, Jan thinks about a “Market News” agent. This could be refactored out of the “Fastvertising” agent, splitting out the logic to query Twitter, Facebook, Google Trends and so on, and ensuring there’s intermediate state summarising the market every hour or so for future agent review. Fortunately, a colleague has already written such an agent, and it is available in the registry. Jan simply installs it, tuning it to his particular use case, and refactors the Fastvertising agent on top of it. In a fit of inspiration, Jan also publishes the Fastervertising agent for others to use.
Jan kicks off a round of backtesting & bechmarking to ensure that this new agent doesn’t introduce regressions with known inputs of the loop. He’ll put up the proposed workflow for review after that loop has been completed. He then goes to lunch.
The remainder of this paper discusses how feasible this is, and paths to get there.
Core
This vision lays out a “value delivery loop” (or just, “loop”). It also illustrates that humans are no longer in the critical path for the delivery of value, and instead are focusing on maintaining the “loop” itself. The marginal value of a human is on the design of the loop, verifying its outcomes, extending it with additional checks or guidance to produce better outputs and taking accountability for the results of the loop.
Loop
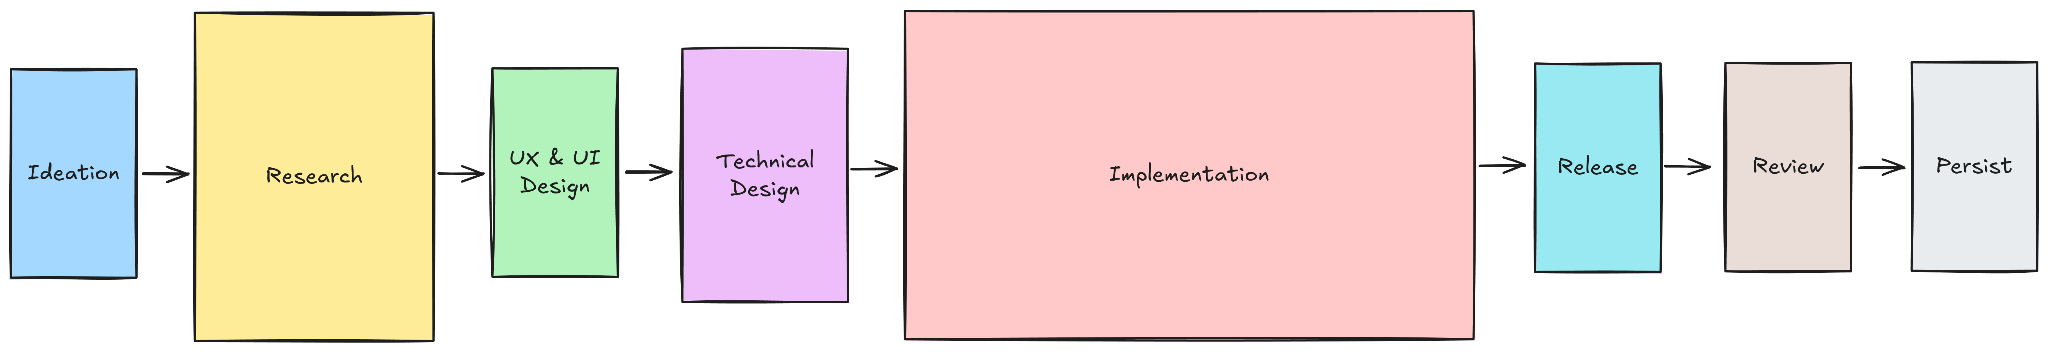
The software development loop consists of:
Ideation: Figuring out what a potentially different future might look like, where the product (may) deliver more value.
Research: Validating if that potential future makes sense, if the assumptions it makes are solid, if there’s prior art, if customers give feedback this would be useful.
UX & UI Design: What a future version of the experience could look like, how the user should progress through it and so on.
Technical Design: What a future technical implementation of this application looks like, with a simplified view and set of assumptions.
Implementation: Implementing the UX, UI and Technical designs, and validating them against those designs.
Release: Putting those changes in front of users, validating them against baselines.
While less frequently employed, there are occasionally two extra steps:
Review: Determining whether the underlying assumptions of the ideation & the research bear out.
Persist: The decision whether to keep the change as the underlying assumptions bear out, or whether to roll it back & abandon it.
With the last two steps only ever meaningfully implemented as “A/B testing”. The software development loop (pre-agents) looks as follows, where larger boxes indicate larger investment.
Batch Reduction
Over time, software engineering has been progressively reducing the size of batches of software work until the current day, where releasing multiple times per day has become the canonical expectation, and for customer facing systems changes are released per-customer and with “feature flags”. This constrains the impact of any work from causing regressions to the existing customer experience, and puts a significant burden on it to improve the customer experience to persist.
Agentification
To determine how far towards the vision we can get, we need to determine how much each stage can be represented in an “agentically deliverable” way. To understand this, we need to model each stage through the artifacts it produces, and how it generates those artifacts and how much that process can be modelled by agents.
Each of the steps can be modelled as an artifact:
Ideation: Issues, Tickets
Research: Papers, surveys, requests for feedback.
UX & UI Design: UX & UI Design: Mockups, small interactive flows.
Implementation: Code
Release: Deployment Artifact, State
Review: Papers
Persist: Persist Decision
Which means, in principle, we can use a large language model to generate all of these steps, and feed each previous step as input to the next. So, the full lifecycle can be delivered. Still, long running tasks tend to produce poor outcomes.
The Harness
The ability to successfully deliver results is a function of:
The Model: More recent models, and those with a higher number of parameters tend to show better results (e.g. Opus 4.6 over Opus 4.5)
The Harness: The feedback loop to the agent guides it to be closer to “on-track”
This is most readily apparent through the lens of software delivery, where the agents produce mostly valid code. With additional checkers (e.g. compilers, linters, unit tests) the agents are much more likely to produce code that is an appropriate output.
Revised Economics
While this paper will (later) discuss the technical innovations required to make this possible, assuming reasonable success at the delivery of each tasks means the economics now look like:
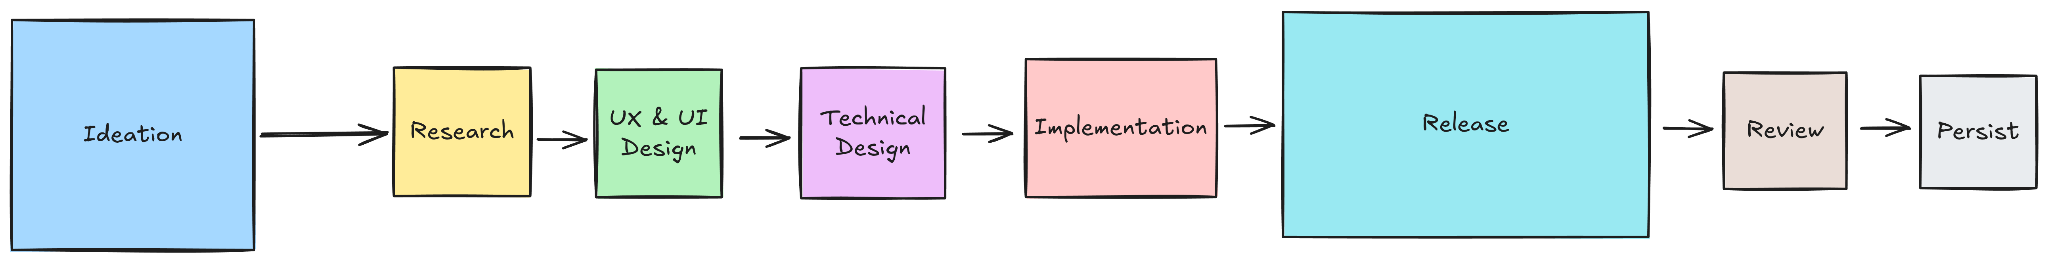
Of the tasks that are traditionally required for the delivery of value, only ideation and release have any meaningful cost associated. For those, the costs are:
Ideation: Imagination. So far, large language models can only blend concepts based on their latent data, versus humans which can be more radical in imagining a different future.
Release: Statistically relevance. It takes some time to trade off between safety, ensuring the CX remains good but allowing innovation.
Even “release” can be somewhat overcome by running releases in parallel and against different populations through A/B tests, but within the boundary of each (potential) change, this is what a potential “future” cost of change could look like.
Implications
There are some remarkable implications of this reduction in total cost:
Experiment Frequency
With the ability to scale up the delivery of value within a loop arbitrarily, the ability to run experiments is no longer gated on engineering time, but rather by release, customers who prefer stability and the idea to generate those experiments. There will invariably be a point where the return on investment is no longer reasonable for additional experiments.
Quality of Work
The delivery of technical work from humans can be remarkably inconsistent. Establishing consistency requires enormous levels of communication, discipline, enforcement and other organizational structures required to persist that discipline. This is often offloaded to other products (via “platform engineering”), but at the loss of engineering autonomy.
With the shift to a more agentic model of engineering, the consequence of any individual decision meaningfully decreases — either because the system can cope with the complexity, or because it’s cheap to reverse and standardize later. In general, LLMs tend to reward consistent work.
Reduction in Complexity
Software complexity tends to grow as a reflection of the size and complexity of the organization (via Conway’s Law). However, as the needs of the organization change, it is very difficult to shrink an organization with a given software complexity down, as it requires that complexity to reduce which in turn requires software rewrites. This can be more possible with the reduction of cost for all software engineering, via something like a “microservice to monolith” approach.
Path
Getting to this vision requires rethinking much of how software delivery works today. However, there are a few clearer and larger layers that need to be built.
Orchestration Layer (Likely: GitHub)
Task Lifecycle
Tasks progress through a linear lifecycle, described above as “the loop”. They need to progress from Ideation → Research, Research → UX/UI design and so on. Tasks need to be serializable to this state so they can be stopped, started, and stage gated.
In all likelihood, this looks like a trello board or simple task tracker.
Task Initiation
Task initiation can come from a variety of places, such as:
Customer Feedback
Loop Team Members
Periodic Analysis
In all cases, ideation (should be) cheap, with ideas that seem to have merit being progressed until they meet the minimum burden of research.
Stage Gates & Review
In order to be able to take accountability for the work and to be able to evolve the loop, humans need to review the work at its different stages. This can be extended with agentic verification as needed.
Appendix
FAQ
What questions does this paper not cover?
Token Economics
The paper makes a clear and nonsensical assumption that large language models (“tokens”) are essentially free (or at least, cheaper than humans). The economics of this are still a few years away from settling.
Is this possible?
I’m not sure yet. I think we’re at a point in history where we’re not going to get any more information about whether it’s possible from the research; what remains is the time and talent dedicated to trying to make it work. The upsides of getting it working are pretty substantial, and the downsides far less than even the delivery of a single significant but bad project.
How do you find the talent to do it?
There are significant problems here. For:
Agentic Talent: This requires meta-cognition; the ability to break down your own skills in deliverable units to teach others (or agents).
Engineering Talent: This requires software engineering skills, understanding large language models, understanding agentic execution, the broad software engineering lifecycle and overlaps with some business domain knowledge. This is mostly Principal+ Talent, that somehow still codes and is excited enough about agents to spend the time self-learning.
Product Talent: This requires deep product knowledge, but with some engineering knowledge and the ability to reason through agents.
Of the many people I have worked with in my career, I can’t think of more than a few of these people.
What’s the risk of “AI Slop” in this design?
Significant. But there’s a duality to “Slop”:
The Good: Large language models reward standardization well. The absolute majority of software can look approximately the same, reusing the same paradigms. There’s far more complexity in software engineering today than the problems fundamentally require.
The Bad: Large language models drift toward standardization where novelty is expected. Standard UIs, generated data and so on can feel impersonal and lazy.
So, there needs to be a “novelty reward” in some aspects of development (e.g. ideation), else things just converge on the reflection of these topics in the latent data in the model(s).
Does “traditional” product development still make sense in a world of agents?
Yes, I think so. Even the most complex agent is essentially still just token prediction and tool execution. I’m not sure that humans, given the choice, would choose to make every interaction conversational. It’s just enjoyable having something resembling the physical world (via a screen) that you can see, and interact with.
Is this linked to a specific organization?
No. So far, I’ve worked in organizations at different levels and at different sizes. What’s changed in this story is that a smaller team focused on “Loop engineering” could, conceptually, wildly out-deliver a larger team delivering via “Agentic Engineering” or via “Agile”.
Large Organizations
Large organizations tend to have a high cost of change, but have meaningfully more capital to expend on alternative designs. This means they’re often experimenting, but with only small deviations from the current operating model (e.g. “Claude Code”).
Funded Startup
The ideal economic unit for this work is likely a small, reasonably well funded startup (tech team ~3 - 8 people) which can work to solve some customer facing problem on behalf of $BIGCO, but working with an independent toolchain, newer, agentic tools and in a new way. This allows
Does this require an “Agentically Native” organization?
Larger organizations will have more challenges shifting from their inertia to a new model of delivering value as it requires significant restructuring of the boundaries of responsibility between job roles, significant development technology and — most critically — a move away from tools optimized for humans to those optimized for agents as their primary audience.
However, an “agentically native” team can co-exist with an “agile” team. To allow both teams to maintain independent velocity, we need to minimize the amount of communication across team boundaries, but strong application guarantees (e.g. long lived, well designed APIs) already solve this.